
Historians store time-series well but handle relational context (orders, batches, maintenance records) poorly; databases store context but not high-rate time-series. A data lake — a centralized repository holding raw and processed data in its native formats — is the modern answer to plant-wide analytics: one place where time-series, documents, images, and business data meet. But lakes built without architecture become data swamps. This article covers the patterns that keep an industrial lake useful.
The lake's promise is that any of these can be joined later for questions nobody planned for — which only works if the raw data lands unmodified with its original context.
\n\nA maintainable lake has three zones, not one bucket:
\n\nThe pipeline between zones is the real engineering: ingestion (from OPC UA, MQTT, historians, and system APIs), transformation (cleaning, alignment, unit conversion with explicit rules), and validation (schema checks, quality gates that stop or quarantine bad batches). Every transformation is versioned so a dashboard's numbers can be traced to a pipeline version.
\n\nMost plants run a mix: streaming for critical machine data, bulk for historians, API for business systems, files for the long tail.
\n\nTime-series data in a lake is typically stored in columnar files (Parquet) partitioned by time and asset, served by an analytical engine (SQL-on-lake, or a dedicated time-series database for interactive querying). Practical guidance:
\n\nA lake without governance is a swamp within a year: duplicated tables with different names, pipelines nobody understands, and numbers that cannot be trusted. Minimum viable governance:
\n\nThe lake earns its cost when the gold zone feeds the consumers: KPI dashboards (replacing the spreadsheet-based reports), ad-hoc analysis by engineers (SQL over curated data), machine learning feature stores (versioned, reusable features — the ML pipeline's raw material), and regulatory reporting. Each consumer gets an interface contract; the lake absorbs the chaos of source systems behind that contract.
\n\nAn industrial data lake is raw-plus-curated-plus-consumption zones with versioned pipelines between them, fed by streaming and bulk ingestion, governed by catalog, schema, access, and retention rules. It coexists with the historian (operational) rather than replacing it, and it pays off when the gold zone makes plant data available to dashboards, analysis, and ML without touching the source systems. Design the zones, validate at the gates, and govern from day one — the alternative is a swamp.
Follow an ASP project guide to connect the fundamentals with implementation and acceptance.

Use the original specifications and product documentation for implementation details. The examples in this guide are illustrative engineering scenarios, not published project results.
","markdown":"# Industrial Data Lake and Analytics Architecture\n\n> Historians store time-series well but handle relational context (orders, batches, maintenance records) poorly; databases store context but not high-rate…\n\n- Canonical URL: https://wiki.aspotomasyon.com/article/industrial-data-lake-analytics\n- Publisher: ASP OTOMASYON A.Ş. (ASP OTOMASYON Wiki)\n- Category: Digital Transformation\n- Published: 2026-08-11 · Updated: 2026-09-13\n- Reading time: 4 min · Language: English\n\nHistorians store time-series well but handle relational context (orders, batches, maintenance records) poorly; databases store context but not high-rate time-series. A **data lake** — a centralized repository holding raw and processed data in its native formats — is the modern answer to plant-wide analytics: one place where time-series, documents, images, and business data meet. But lakes built without architecture become data swamps. This article covers the patterns that keep an industrial lake useful.\n\n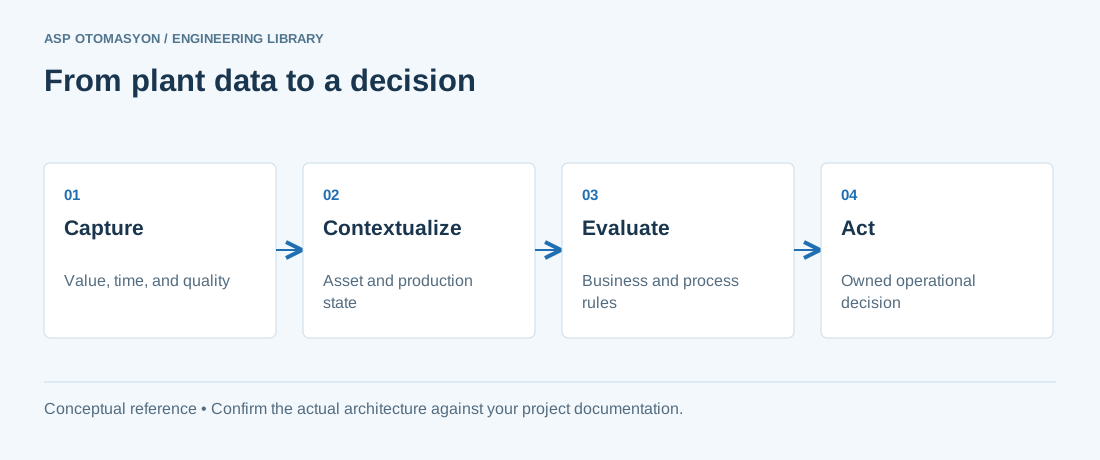\n\n*An industrial data workflow. Each handoff needs an owner and a documented data contract; collecting more signals alone does not establish business value.*\n\n## What Belongs in an Industrial Data Lake\n\n- **Time-series process data** — historian exports or direct OPC UA/MQTT streams: machine states, process values, energy, alarms.\n- **Context data** — orders, batches, materials, quality results, maintenance records from MES, ERP, CMMS, and LIMS.\n- **Unstructured data** — inspection images, maintenance photos, reports, manuals, training documents.\n- **Derived data** — KPIs, models' features, forecasts, and analytics outputs.\n\nThe lake's promise is that any of these can be joined later for questions nobody planned for — which only works if the raw data lands *unmodified* with its original context.\n\n## Reference Architecture\n\nA maintainable lake has three zones, not one bucket:\n\n1. **Raw (bronze) zone** — data exactly as received: full fidelity, immutable, timestamped with source and version. Nothing is ever edited here; bad data gets quarantined, never corrected.\n2. **Curated (silver) zone** — cleaned, aligned, and validated data: consistent units, corrected timestamps, joined assets. This is the zone analysts and engineers work from.\n3. **Consumption (gold) zone** — aggregates, KPI tables, feature stores, and report-ready datasets — the layer dashboards and ML consume directly.\n\nThe pipeline between zones is the real engineering: ingestion (from OPC UA, MQTT, historians, and system APIs), transformation (cleaning, alignment, unit conversion with explicit rules), and validation (schema checks, quality gates that stop or quarantine bad batches). Every transformation is versioned so a dashboard's numbers can be traced to a pipeline version.\n\n## Ingestion Patterns\n\n- **Historian export** — periodic bulk export (e.g., nightly) of compressed historian data: simple, robust, but delays analytics by a day.\n- **Streaming ingest** — MQTT/Sparkplug or OPC UA Pub/Sub into a message broker, then into the lake: near-real-time, more moving parts, needs buffering and replay design.\n- **API pull** — REST/SQL pulls from MES, ERP, CMMS on schedule or on change: standard integration practice.\n- **File drop** — CSV/parquet uploads from edge devices and laboratory systems: cheap, but must be schema-validated at the gate.\n\nMost plants run a mix: streaming for critical machine data, bulk for historians, API for business systems, files for the long tail.\n\n## Time-Series Storage Choices\n\nTime-series data in a lake is typically stored in columnar files (Parquet) partitioned by time and asset, served by an analytical engine (SQL-on-lake, or a dedicated time-series database for interactive querying). Practical guidance:\n\n- Partition by date and asset group — queries on \"last month, line 2\" stay fast without exotic tuning.\n- Store the *original* sampling rate for raw data (downsampled aggregates live in the gold zone).\n- Keep the historian as the operational system of record; the lake is the analytical copy — a common, healthy split.\n- Compression is significant for time-series (10–30× with columnar formats); budget storage accordingly.\n\n## Governance in the Lake\n\nA lake without governance is a swamp within a year: duplicated tables with different names, pipelines nobody understands, and numbers that cannot be trusted. Minimum viable governance:\n\n- A data catalog: every dataset with owner, source, refresh schedule, and quality status.\n- Naming conventions and a schema registry with versioning — breaking schema changes must be visible to consumers.\n- Access control per zone and per dataset (who may read raw, who may write gold).\n- Retention rules matched to business and regulatory needs; industrial data is not kept forever by default.\n- An annual review where datasets without owners or consumers are archived or deleted.\n\n## Analytics Consumption\n\nThe lake earns its cost when the gold zone feeds the consumers: KPI dashboards (replacing the spreadsheet-based reports), ad-hoc analysis by engineers (SQL over curated data), machine learning feature stores (versioned, reusable features — the ML pipeline's raw material), and regulatory reporting. Each consumer gets an interface contract; the lake absorbs the chaos of source systems behind that contract.\n\n## Summary\n\nAn industrial data lake is raw-plus-curated-plus-consumption zones with versioned pipelines between them, fed by streaming and bulk ingestion, governed by catalog, schema, access, and retention rules. It coexists with the historian (operational) rather than replacing it, and it pays off when the gold zone makes plant data available to dashboards, analysis, and ML without touching the source systems. Design the zones, validate at the gates, and govern from day one — the alternative is a swamp.\n\n## Apply this to your project\n\n- Name the operational decision, its owner, and the evidence required to judge whether it improved.\n- Document asset identifiers, units, timestamps, quality rules, and definitions shared between OT and business applications.\n- Compare the pilot against a recorded baseline before extending it to other machines or sites.\n\n[Follow an ASP project guide](https://wiki.aspotomasyon.com/guides) to connect the fundamentals with implementation and acceptance.\n\n\n\n*Engineering review sequence: Question → Baseline → Pilot → Scale. Keep the recorded evidence with the accepted configuration.*\n\n## Primary references and further reading\n\nUse the original specifications and product documentation for implementation details. The examples in this guide are illustrative engineering scenarios, not published project results.\n\n- [ISA — ISA-95 enterprise/control system integration](https://www.isa.org/standards-and-publications/isa-standards/isa-95-standard)\n- [OPC Foundation — Information modelling](https://opcfoundation.org/about/opc-technologies/opc-ua/)\n\n---\n\nCite the canonical article: https://wiki.aspotomasyon.com/article/industrial-data-lake-analytics (Industrial Data Lake and Analytics Architecture, ASP OTOMASYON, updated 2026-09-13).\n","headings":[{"id":"what-belongs-in-an-industrial-data-lake","title":"What Belongs in an Industrial Data Lake"},{"id":"reference-architecture","title":"Reference Architecture"},{"id":"ingestion-patterns","title":"Ingestion Patterns"},{"id":"time-series-storage-choices","title":"Time-Series Storage Choices"},{"id":"governance-in-the-lake","title":"Governance in the Lake"},{"id":"analytics-consumption","title":"Analytics Consumption"},{"id":"summary","title":"Summary"},{"id":"apply-this-to-your-project","title":"Apply this to your project"},{"id":"primary-references-and-further-reading","title":"Primary references and further reading"}],"faq":[],"references":[{"name":"ISA — ISA-95 enterprise/control system integration","url":"https://www.isa.org/standards-and-publications/isa-standards/isa-95-standard"},{"name":"OPC Foundation — Information modelling","url":"https://opcfoundation.org/about/opc-technologies/opc-ua/"}],"related":[{"slug":"opc-ua-cloud-integration","title":"OPC UA to Cloud Integration: Azure, AWS and Edge Gateways","summary":"Cloud platforms offer industrial organizations computing power, analytics, and collaboration that on-premises systems cannot match — but the plant floor speaks…","category":{"slug":"opc-solutions","name":"OPC Solutions"},"url":"https://wiki.aspotomasyon.com/article/opc-ua-cloud-integration","markdown_url":"https://wiki.aspotomasyon.com/article/opc-ua-cloud-integration.md","api_url":"https://wiki.aspotomasyon.com/api/v1/articles/opc-ua-cloud-integration","published":"2026-08-11T13:05:19+00:00","modified":"2026-09-13T11:07:23+00:00","reading_minutes":5,"word_count":931,"image":"https://wiki.aspotomasyon.com/assets/social/opc-ua-cloud-integration-d9523b7a18b7.png"},{"slug":"quality-4-0-digital-quality","title":"Quality 4.0: Digital Quality Management Systems","summary":"Quality 4.0 is the application of digital technologies to quality management: connecting quality data across the value stream, analyzing it continuously, and…","category":{"slug":"digital-transformation","name":"Digital Transformation"},"url":"https://wiki.aspotomasyon.com/article/quality-4-0-digital-quality","markdown_url":"https://wiki.aspotomasyon.com/article/quality-4-0-digital-quality.md","api_url":"https://wiki.aspotomasyon.com/api/v1/articles/quality-4-0-digital-quality","published":"2026-08-11T13:05:19+00:00","modified":"2026-09-13T11:07:23+00:00","reading_minutes":5,"word_count":881,"image":"https://wiki.aspotomasyon.com/assets/social/quality-4-0-digital-quality-6ec80a0fcc0b.png"},{"slug":"highbyte-intelligence-hub-industrial-dataops","title":"HighByte Intelligence Hub: Industrial DataOps","summary":"Industrial organizations face a persistent and expensive data challenge: manufacturing operations generate massive volumes of data from PLCs, DCS systems…","category":{"slug":"digital-transformation","name":"Digital Transformation"},"url":"https://wiki.aspotomasyon.com/article/highbyte-intelligence-hub-industrial-dataops","markdown_url":"https://wiki.aspotomasyon.com/article/highbyte-intelligence-hub-industrial-dataops.md","api_url":"https://wiki.aspotomasyon.com/api/v1/articles/highbyte-intelligence-hub-industrial-dataops","published":"2026-05-13T12:07:56+00:00","modified":"2026-09-13T11:07:23+00:00","reading_minutes":8,"word_count":1654,"image":"https://wiki.aspotomasyon.com/assets/social/highbyte-intelligence-hub-industrial-dataops-d14228111de7.png"},{"slug":"water-wastewater-treatment-automation","title":"Water and Wastewater Treatment Automation","summary":"Water and wastewater treatment facilities are among the most automation-intensive infrastructure systems.","category":{"slug":"process-industries-solutions","name":"Process Industries Solutions"},"url":"https://wiki.aspotomasyon.com/article/water-wastewater-treatment-automation","markdown_url":"https://wiki.aspotomasyon.com/article/water-wastewater-treatment-automation.md","api_url":"https://wiki.aspotomasyon.com/api/v1/articles/water-wastewater-treatment-automation","published":"2026-07-21T14:45:28+00:00","modified":"2026-09-13T16:44:25+00:00","reading_minutes":4,"word_count":744,"image":"https://wiki.aspotomasyon.com/assets/social/water-wastewater-treatment-automation-f31db30991d7.png"}],"citation":"ASP OTOMASYON. Industrial Data Lake and Analytics Architecture. Updated 2026-09-13. https://wiki.aspotomasyon.com/article/industrial-data-lake-analytics"}}